How to debug production errors with Codex
Use Codex to investigate production errors with captured requests, logs, and release context. A practical DebugBundle workflow from incident to tested fix.
By Owen Far
You open a repository in Codex and ask it to fix a production error. The code is there. The failed request, the warning just before it, and the version running on the server may be somewhere else.
Those details change where the investigation starts. A stack trace points to a line of code. The surrounding evidence helps explain how execution reached it.
We're adding dedicated Codex support to DebugBundle to make that evidence easier to bring into the conversation. Here's a practical way to use it.
Start with one failure
Our example checkout bundle contains a request that returned a 500 response, a null currency access, and an earlier warning: No pricing configuration found for shipping country.
It's a synthetic example, but the debugging question is useful: what should checkout do when pricing configuration is missing for the requested country?
Codex can inspect that path and the intended behavior before proposing a change. Adding a null check might prevent the exception while leaving checkout unable to complete. The warning gives the investigation something more specific to follow.
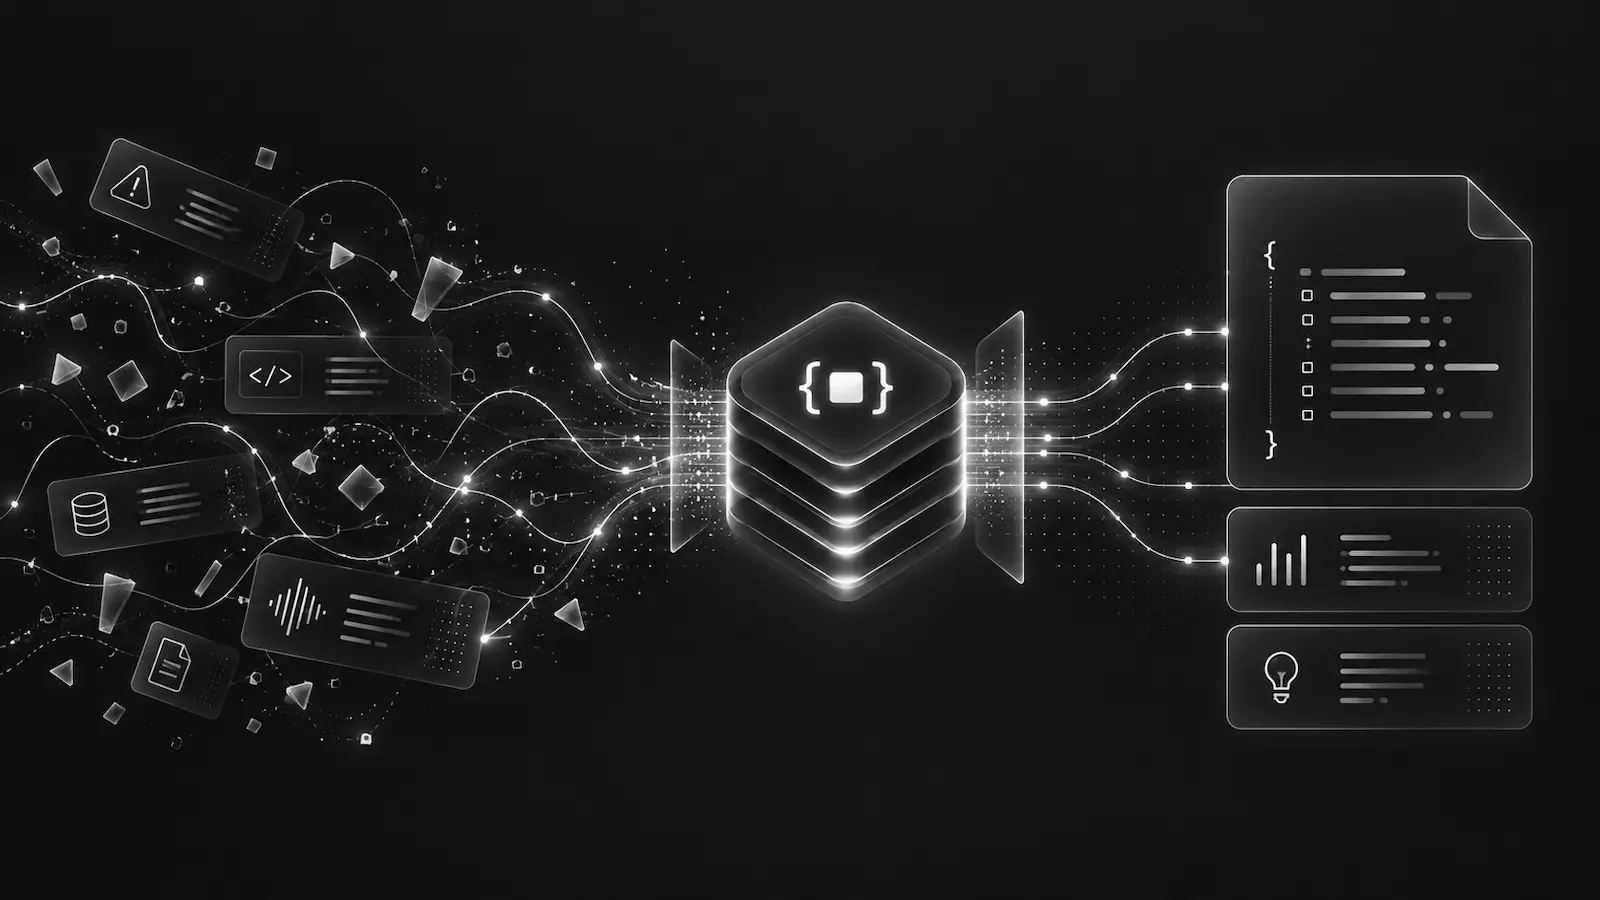
A debug bundle brings the captured error, request, related logs, and available release context together. It also makes missing evidence visible. A field that wasn't captured should stay unknown.
Connect the evidence to your repository
The Codex developer plugin combines DebugBundle's MCP connection with a debugging workflow skill. You can also configure MCP directly. The Codex setup guide covers both paths and authentication.
Your application needs capture set up first. Installing the plugin alone won't create incidents. If you're starting fresh, follow the quickstart and capture a controlled test failure.
Open Codex in the application repository. Choose local evidence or the intended hosted project, service, and environment, then retrieve one incident's bundle. Check the captured release against the code you're about to edit.
Give Codex a focused task
Once the connection is configured, try a prompt like this, replacing the service and environment:
Use this repository's DebugBundle setup to investigate the latest open incident for [service] in [environment]. Read its bundle and available reproduction details before proposing a fix. Explain the likely cause and any missing evidence. Add a regression test for the intended behavior, make a focused change, and report which tests passed. Leave deployment and incident resolution for review.
For the checkout example, the test should cover the missing pricing configuration and what the application is supposed to do about it. That gives you something concrete to review alongside the patch.
Verify the fix in stages
A passing local test is useful evidence. Confirming that the production failure has stopped requires a separate check after deployment.
If the bundle includes a request replay, review its destination and effects before using it. A captured checkout request can change state; reproduce it in a controlled environment with test data.
Start by inspecting the example bundle. If it contains the context you usually end up copying into chat, follow the Codex setup guide and try the workflow on one incident from your own application.