What is a debug bundle? Production evidence for coding agents
See how a debug bundle packages a production error, request, logs, and release context into structured evidence a coding agent can inspect.
By Owen Far
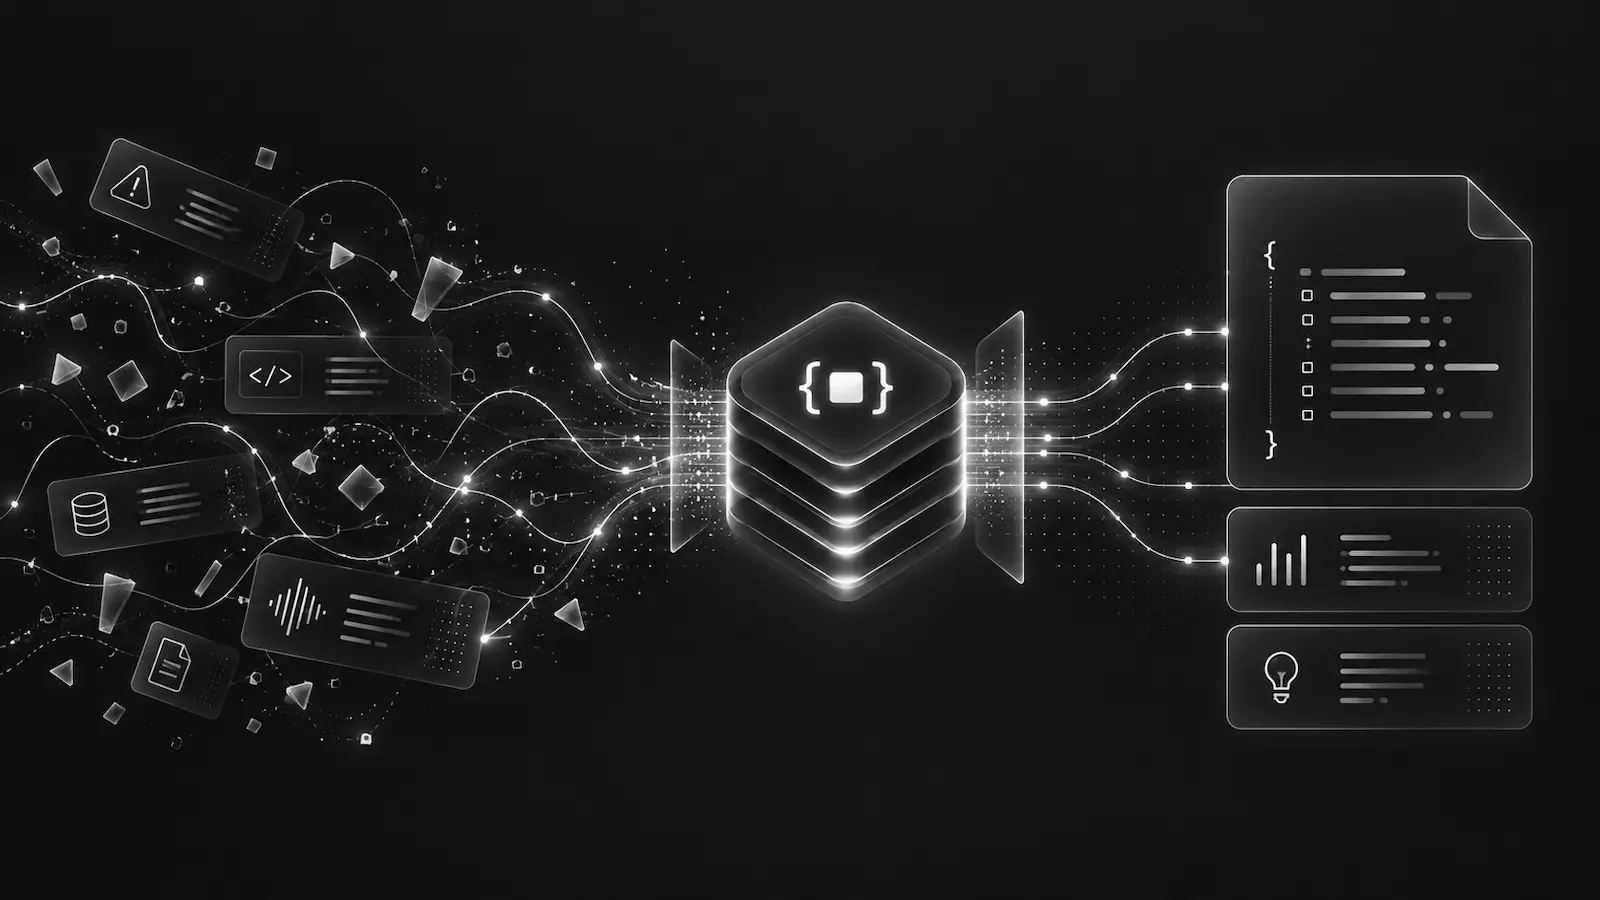
A debug bundle is a bounded, structured package of captured evidence for a production incident. It brings the failure and relevant context together so a developer or coding agent can start investigating without assembling that context by hand.
In DebugBundle, that package is versioned JSON. It can include the error, request, related logs, runtime and release details, redaction information, and request replay artifacts when enough context was captured.
Your coding agent can read the repository. The bundle gives it something else: evidence of what happened when that code ran.
Start with a failed checkout
The example on our homepage shows a checkout request returning a 500 response. You can also inspect the full JSON bundle.
This is a synthetic example, not a customer incident or a demonstrated fix. These are selected fields from it, not a complete schema-valid bundle:
{
  "bundle_version": 1,
  "bundle_type": "failure",
  "context": {
    "request": {
      "method": "POST",
      "path": "/checkout",
      "body": {
        "cart_id": "cart_demo",
        "shipping_country": "DE"
      }
    },
    "response": { "status_code": 500 },
    "error": {
      "name": "TypeError",
      "message": "Cannot read properties of null (reading 'currency')"
    },
    "deploy": { "deploy_version": "checkout-1.4.0" }
  },
  "verification": {
    "synthetic": true,
    "local_verified": false,
    "production_verified": false
  }
}
The full artifact also contains an application frame pointing to createCheckout in src/checkout.ts:42, and a warning just before the failure: No pricing configuration found for shipping country.
Together, those details suggest a useful first investigation: inspect how checkout handles missing pricing configuration for the captured shipping country. That is a hypothesis to test, not a proven root cause.
| Captured evidence | What to investigate | What it does not establish |
|---|---|---|
POST /checkout, response 500 | The failing request path | Why it failed |
Null currency access and an application frame | The value used in createCheckout | That changing this line alone is the right fix |
| Warning about missing pricing configuration | Configuration lookup and failure handling | A confirmed cause |
Release checkout-1.4.0 | The code and configuration for that release | That this deployment introduced a regression |
| Redacted authorization header | What a controlled replay would need | Permission to replay against production |
Notice what is missing, too. The example has no captured request ID or response duration. An agent should not fill those gaps with guesses.
What belongs in a useful bundle?
Start with the questions you would ask another developer about the failure:
- What triggered it: an exception, failed request, or another captured signal?
- Where did it surface, and which application frames are available?
- Which request, service, runtime, and release were involved?
- What related logs or breadcrumbs were captured?
- What was removed by redaction, and what was never captured?
- Is there enough request context to prepare a replay?
Not every incident will have every field. Capture configuration and SDK support affect what is available. The goal is a useful boundary around the evidence, not a dump of everything the application knows.
For field-level details, see the bundle schema reference.
Why structure helps a coding agent
A stack trace, an alert, and a log search can each be useful. The work often starts with connecting them: finding the request, matching the release, and deciding which nearby log lines actually belong to the incident.
A structured incident bundle puts the captured pieces in named fields. The agent can distinguish the error from the request body, and the captured release from a suggested explanation. A human reviewing its proposal can inspect that same evidence.
This does not mean the bundle contains the answer. In the checkout example, the agent still needs to read the relevant code, understand the intended pricing behavior, and test a proposed change. The bundle gives that investigation a concrete starting point.
Deterministic evidence is not a deterministic diagnosis
In DebugBundle, the same inputs produce the same bundle. That makes the artifact useful for repeatable inspection and test fixtures.
An incident's active bundle can still change when new evidence arrives. If you need to review exactly what an agent saw, retain the particular artifact used in that investigation.
The distinction matters: stable evidence does not guarantee that an agent will reach the same conclusion every time, or that its suggested fix is correct. Those are separate questions that need review and tests.
Request replay has limits
When sufficient request context is available, DebugBundle can generate cURL, HTTPie, and JSON replay artifacts. These describe the captured request. They do not reconstruct the whole application environment.
The checkout example uses an .invalid hostname and redacted credentials. It is deliberately not a command to run unchanged. A useful test would need a controlled environment, appropriate test credentials, and the relevant cart and pricing state.
Timing, external services, and database state can all affect whether the failure appears again. A replay confidence value is not proof that a reproduction was tested. This example explicitly marks both local and production verification as false.
Use the captured request to build a controlled test, then check whether the proposed change handles the intended behavior. Do not replay a purchase or another state-changing production request simply because a command is available. The reproduction guide explains the artifacts and their requirements.
One artifact, several ways to inspect it
Developers can inspect bundles through the dashboard, CLI, or API. Coding agents can retrieve them through MCP. Available actions depend on the deployment and the connection's permissions.
That means a developer and an agent can work from the same captured artifact while using different interfaces. The agent workflows guide explains the broader workflow; the MCP debugging article covers the access path.
Logs still belong in this workflow. They become evidence attached to a particular incident rather than an unbounded transcript. Redaction and capture controls help limit exposure, but review real bundles before sharing them outside the intended team or tool.
Capture your first bundle
A debug bundle is most useful when a production failure is hard to understand from the repository alone. If the problem is already reproducible in a local unit test, start there. You do not need production capture to investigate every bug.
To see whether this workflow helps your application, follow the DebugBundle quickstart, capture a controlled test failure, and inspect its bundle. Can you identify the failing path, the relevant context, and what you still need to check? That is the first useful result to aim for.
Debug production errors with your AI agent
DebugBundle captures errors and their surrounding context in structured debug bundles, giving your coding agent the evidence to investigate.
Open source · Start free